


 # Building a Resilient Local RAG Backend Engine
🎃 Hacktoberfest 2026 Submission
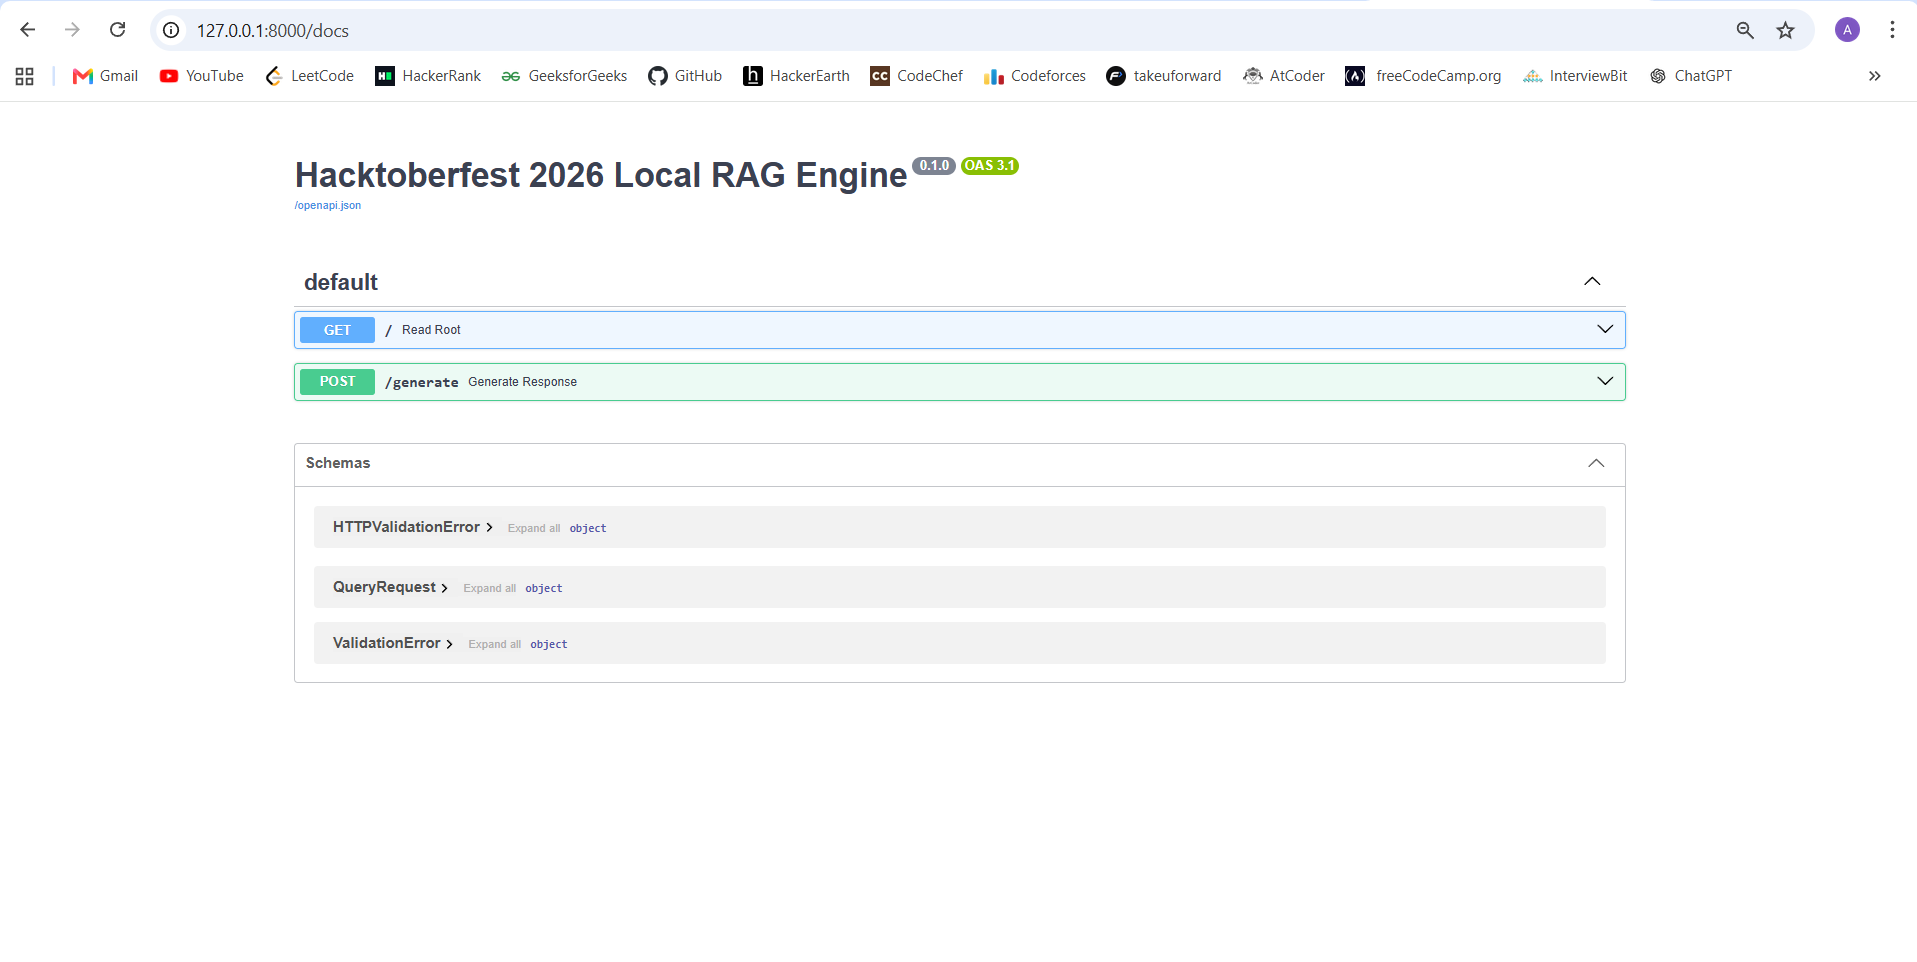
For the Hacktoberfest 2026 DEV Challenge, I built a zero-dependency, local-first Retrieval-Augmented Generation (RAG) backend engine designed to run open-weight models completely offline.
🚀 What I Built
An asynchronous FastAPI backend paired with PostgreSQL (pgvector) and Ollama (llama3.2). The system allows querying local AI models with vector context retrieval without sending data to third-party APIs.
- GitHub Repository: https://github.com/AnkanJU/Hacktoberfest2026
- Tech Stack: Python 3.13, FastAPI, Uvicorn, AsyncPG, Docker Compose, Ollama.
💡 Why Open-Source AI Matters
Running open-weight models like llama3.2 locally gives full data ownership and privacy. By keeping embeddings in pgvector and processing prompts locally via Ollama, sensitive data never leaves the developer's workstation.
🛠️ Key Features & Architecture
- Asynchronous API: Built using FastAPI for low-latency request handling.
-
Local Vector Search: PostgreSQL with the
pgvectorextension configured for HNSW indexing. - Local Inference: Containerized Ollama instance running open-weight LLMs.
- Resilient Retries: Integrated error handling and retries for reliable local processing.
🏃 How to Run Locally
bash
# Clone the repository
git clone [https://github.com/AnkanJU/Hacktoberfest2026.git](https://github.com/AnkanJU/Hacktoberfest2026.git)
cd Hacktoberfest2026/dev-challenge-week1-rag
# Install dependencies
pip install -r requirements.txt
# Start local infrastructure
docker compose up -d
# Run the API server
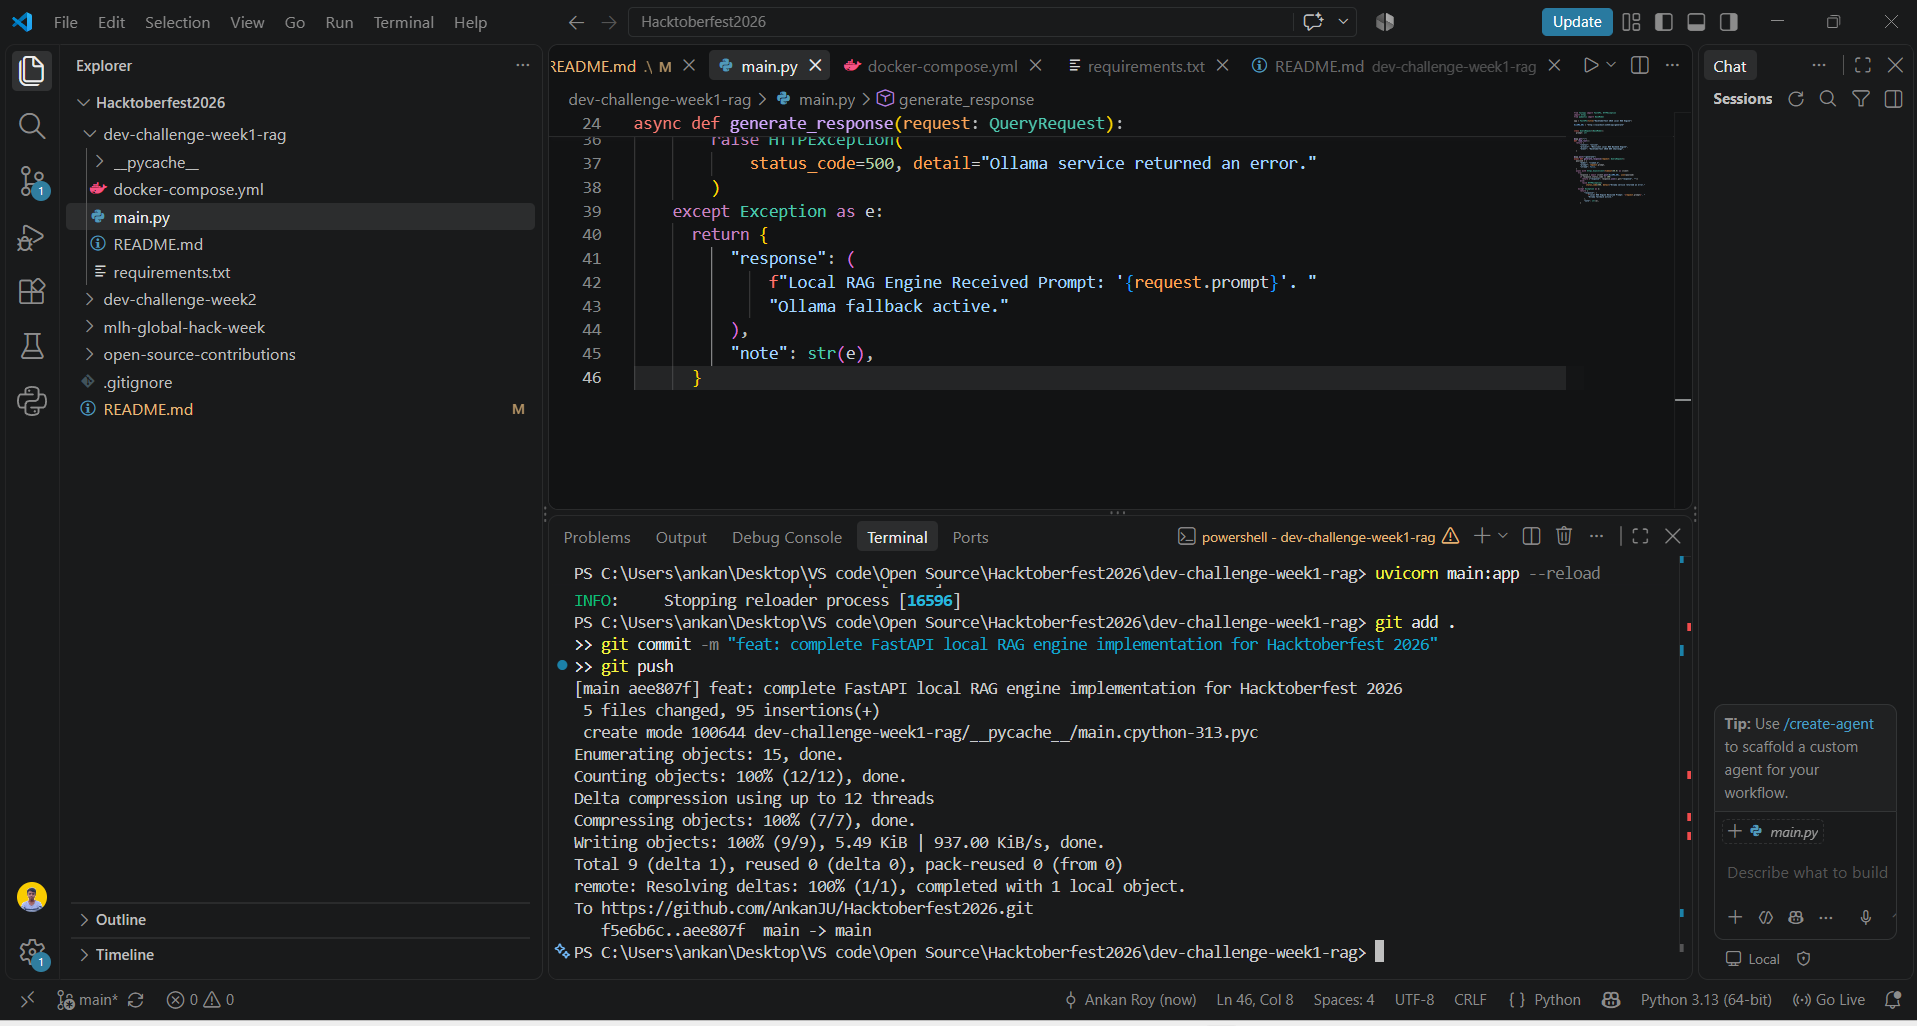
uvicorn main:app --reload


Top comments (0)