


You add a recurring job to a Node.js service. It works on your laptop. Then you deploy three replicas, and all three run the job.
Each process has its own timer. Without shared coordination, none of them knows that another instance is already handling the same scheduled work.
I built Anarchon for this situation. It lets you define cron, interval, and one-off jobs inside your existing service instances. A shared datastore decides which instance wins each execution attempt; the application does not elect a scheduler leader:
import { RedisBackend, Scheduler } from 'anarchon';

const scheduler = new Scheduler({
  backend: new RedisBackend({ redis: process.env.REDIS_URL }), // or Valkey, Postgres, SQLite, RabbitMQ, NATS
});

scheduler
  .every('sync-orders', '30s', async (ctx) => { /* runs on one replica per 30s slot */ })
  .cron('daily-report', '0 8 * * *', async (ctx) => { /* runs once at 08:00 */ }, { timezone: 'Europe/Athens' });

await scheduler.start();
In this tutorial, we will run three processes on one machine (using Node's built-in SQLite so you don't need Docker), stop a winning runner gracefully, and then crash another with kill -9. We will also look at why selecting one runner is different from guaranteeing exactly-once side effects.
The unit of coordination is a scheduled slot
Imagine a job named sync that runs every ten seconds. Anarchon aligns interval schedules to a shared UTC grid: :00, :10, :20, and so on. The intended execution time is the job's slot.
Instances registering the same job name and schedule compete for the same slot in a shared store. Each waits a small randomized delay before claiming it. The store processes the claim atomically, so one instance wins that attempt.
With a lease-enabled backend, the winner periodically renews its lease while it runs. Other instances watch as backups and can try to take over if that renewal stops. There is no elected application leader, but there is shared state and there are renewable leases.
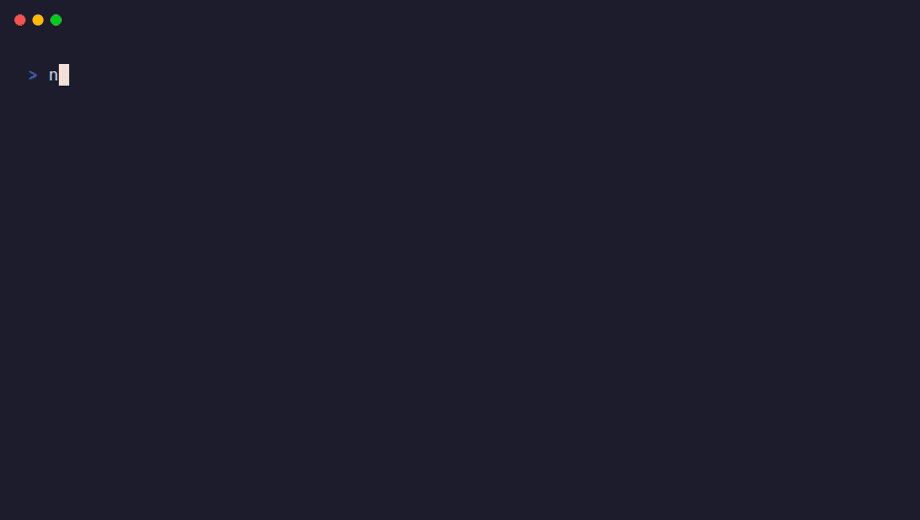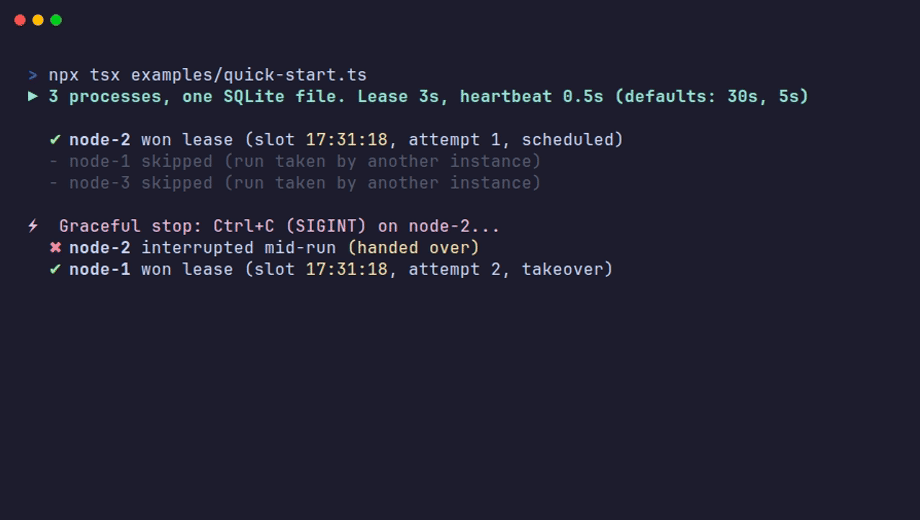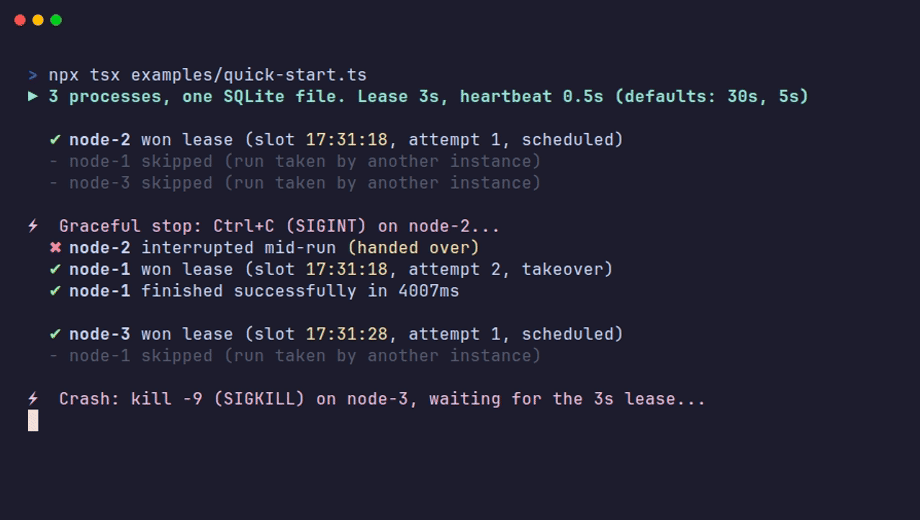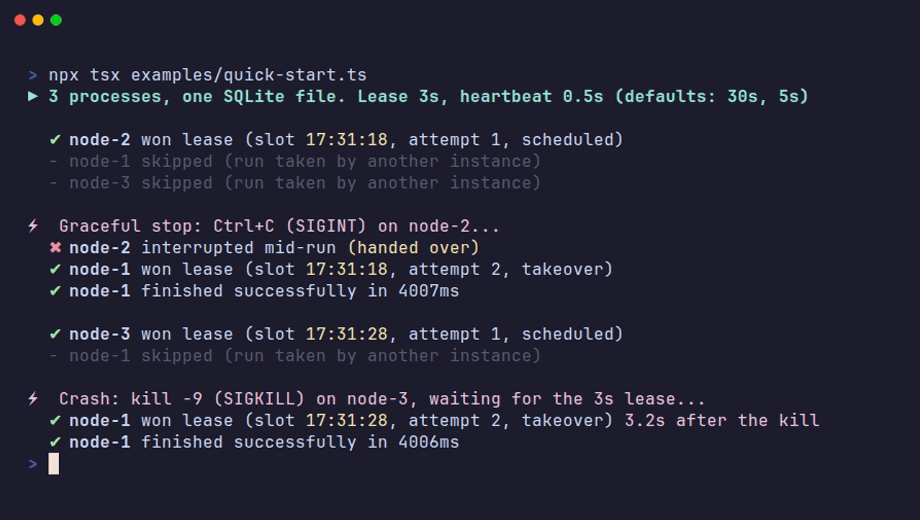
Here is the repository's three-process quick-start recording showing one winner per slot, a graceful handover, and recovery after kill -9—below, we will build a two-job version from scratch and test both failure modes by hand:

1. Create a local project
Use Node.js 22.13 or newer for this example's built-in SQLite driver. You do not need to start Redis or PostgreSQL.
mkdir anarchon-demo
cd anarchon-demo
npm init -y
npm install anarchon@0.4.1
npm install --save-dev tsx
SQLite is convenient here because three local processes can open the same file. This is a same-machine demonstration. For replicas on different machines, use a shared backend such as Redis, Valkey, or PostgreSQL.
2. Define the jobs
Create app.ts:
import { Scheduler, SqliteBackend } from 'anarchon';

const sleep = (ms: number) => new Promise((resolve) => setTimeout(resolve, ms));

async function main() {
  const scheduler = new Scheduler({
    backend: new SqliteBackend({ database: './jobs.db' }),
    leaseMs: 6_000,
    heartbeatMs: 1_000,
    log: true,
  });

  scheduler.every('sync', '10s', async () => {
    await sleep(200);
  }, { catchUpMs: 0 });

  scheduler.every('report', '30s', async (ctx) => {
    console.log(`[handler] report slot=${ctx.slot} attempt=${ctx.attempt} pid=${process.pid}`);
    for (let second = 0; second < 12; second++) {
      ctx.signal.throwIfAborted();
      await sleep(1_000);
    }
  }, { catchUpMs: 0 });

  let stopping = false;
  const shutdown = async () => {
    if (stopping) return;
    stopping = true;
    try {
      await scheduler.stop();
      process.exit(0);
    } catch (error) {
      console.error(error);
      process.exit(1);
    }
  };

  process.on('SIGINT', () => { void shutdown(); });
  process.on('SIGTERM', () => { void shutdown(); });
  await scheduler.start();
  console.log(`ready: ${scheduler.instanceId}`);
}

main().catch((error) => {
  console.error(error);
  process.exit(1);
});
There are two jobs: a short sync every ten seconds and a twelve-second report every thirty seconds.
The six-second lease and one-second heartbeat make recovery easier to watch. They are demonstration settings; the documented defaults are a thirty-second lease and a five-second heartbeat. A shorter lease detects a missing runner sooner but tolerates shorter pauses before another attempt may take over.
I disabled startup catch-up for these jobs with catchUpMs: 0, so the first output is easier to interpret. Wait for the next scheduled boundary after starting them.
3. Run three instances
Open three terminals in the same project directory, and run this in each:
npx tsx app.ts
The directory matters. Each process opens ./jobs.db; different working directories could create different databases and defeat the coordination.
For a normal sync slot, one process reports a start and completion, while the others report that the run was taken. For report, the handler also prints the slot, attempt number, and process ID. Your actual values will differ, but the line has this shape:
[handler] report slot=1791916500000 attempt=1 pid=4123
The randomized delay gives different instances opportunities to win. It is not a promise of perfectly uniform distribution; timing and datastore latency also affect who wins.
4. Stop the winner gracefully
Wait for a report handler to start, then promptly press Ctrl+C in that terminal.
The shutdown handler calls scheduler.stop(). The running job notices its aborted signal at the next check and throws. This allows the run to be handed over. A surviving instance can then claim another attempt without waiting for the entire lease to expire.
Look for a handler line in one of the surviving terminals with the same slot, attempt=2, and a different process ID:
# Terminal 1 (interrupted with Ctrl+C):
[handler] report slot=1791916500000 attempt=1 pid=4123

# Terminal 2 (takes over within two heartbeats):
[handler] report slot=1791916500000 attempt=2 pid=4129
The report starts its twelve-second loop again from the beginning; it does not resume at the iteration where the first process stopped.
Let the replacement finish, then restart the stopped process with npx tsx app.ts.
5. Crash a runner
Wait for the next report to start. From a fourth terminal, kill the PID printed by that handler. On Linux or macOS:
kill -9 <pid>
Do this shortly after the handler starts, so there is time to observe recovery before the next thirty-second slot. Use the printed application PID, not an npx wrapper's PID.
This time, no shutdown handler runs. The remaining instances wait for the last renewed lease to expire and then detect that they can attempt a takeover.
With these settings, expect a delay on the order of the six-second lease plus backup-check timing. One of the surviving terminals will print attempt=2 for that same slot once the lease expires.
Again, compare the slot and attempt. A later slot starting at attempt=1 is a new scheduled run, not recovery of the one you killed. Under the documented rules, a newer run can supersede an unfinished older one.
One winner does not make side effects exactly once
Suppose an application sends an email and crashes before recording success. A replacement attempt cannot generally know whether the email was sent. Repeating the handler may send it again.
Anarchon's execution context provides a stable slot for retries of the same scheduled run. For work scoped to one item per slot, a useful idempotency key can include the job name, slot, and item identity:
const key = `${ctx.name}:${ctx.slot}:${itemId}`;
That key only helps if the system performing the side effect enforces it. Use the external provider's idempotency support, or a database design that atomically couples the relevant state change with duplicate prevention. A separate “already processed?” check followed by an external call leaves a race and a crash window.
Choose the key according to your business operation. If an item must be processed once across all slots, its stable operation identity may be more appropriate than a slot-based key.
ctx.signal is cooperative cancellation. Checking it helps a stale or stopped runner exit, but it does not undo earlier effects or make the next external operation atomic with lease ownership.
There are other deliberate limits:
- With the default overlap policy on lease backends, a new slot is skipped while an earlier run retains a live lease.
- A paused runner can briefly overlap a replacement when it wakes up.
- Recovery is bounded by attempts and run eligibility; it is not an unconditional promise that every slot eventually finishes.
- Startup catch-up covers the latest eligible missed slot when an instance starts within its configured
catchUpMswindow, not every missed occurrence. - Datastore durability and configuration affect the coordination guarantee.
The guarantees page explains those boundaries.
Use an existing Redis, Valkey, or PostgreSQL server
The job definitions stay the same when you change the backend. Install the appropriate driver and pass the backend to new Scheduler({ backend }).
For Redis or Valkey:
npm install redis
Add RedisBackend (or ValkeyBackend) to the import and replace the scheduler construction with:
const scheduler = new Scheduler({
  backend: new RedisBackend({ redis: process.env.REDIS_URL }),
  log: true,
});
All replicas must point to the same intended store and scheduling namespace (prefix). In production, configure the connection through your application's configuration system.
For PostgreSQL:
npm install pg
Add PostgresBackend to the import and use:
const connection = process.env.DATABASE_URL;
if (!connection) throw new Error('DATABASE_URL is required');

const scheduler = new Scheduler({
  backend: new PostgresBackend({ connection }),
  log: true,
});
These replacements use the default lease and heartbeat settings, so crash recovery will take longer than in the six-second SQLite demonstration.
Scheduler<B> infers its capabilities from the backend you pass: lease-only options (overlap, maxAttempts, catchUpMs, leaseMs, heartbeatMs) are only offered on backends with leases, and unsupported or unknown options are rejected instead of silently ignored.
Backend capabilities and how each one selects a single winner:
| Backend | How one instance wins | Leases & takeover |
|---|---|---|
Redis / Valkey (lease, default) |
Lua script reading and writing the slot state atomically | Yes |
| PostgreSQL | Short transaction serialized on the job's row | Yes |
| SQLite / libSQL |
BEGIN IMMEDIATE transaction (single writer) |
Yes |
| RabbitMQ | Single-message gate queue (x-max-length: 1, reject-publish) + publisher confirm |
No (claim only) |
| NATS JetStream | Publish deduplicated by Nats-Msg-Id: <job>:<slot>
|
No (claim only) |
Simple Redis / Valkey strategies (stream-id, idmp on Redis 8.6+, script) |
Stream entry ID, idempotency key, or Lua stream check | No (claim only) |
See the backend overview for requirements and limitations.
Cron expressions, decorators, and NestJS
Intervals are one scheduling option. To add a weekday cron job without decorators, register it on the Scheduler instance before scheduler.start():
scheduler.cron(
  'weekday-digest',
  '0 8 * * 1-5',
  async (ctx) => {
    console.log('digest slot:', ctx.scheduledAt.toISOString());
  },
  { timezone: 'Europe/Athens', catchUpMs: 0 },
);
If you like the NestJS flavor of @nestjs/schedule—where jobs are declared right on class methods—you may have hit its multi-replica catch: @nestjs/schedule runs every @Cron() method on every instance. Anarchon provides a familiar decorator API (@Cron, @Every, and @At) backed by shared slot coordination. Note the import: Cron comes from anarchon, not @nestjs/schedule.
With the decorator API, methods declare their own schedules (with standard TypeScript decorators, new ReportsService() registers jobs automatically with no reflect-metadata; in NestJS or with "experimentalDecorators": true, add @Scheduled() to the class):
import { Injectable } from '@nestjs/common';
import { Cron, Every, type JobContext, Scheduled } from 'anarchon';

@Injectable()
@Scheduled() // needed for NestJS / legacy experimentalDecorators; optional with standard TS decorators
export class ReportsService {
  @Cron('weekday-digest', '0 8 * * 1-5', { timezone: 'Europe/Athens' })
  async digest(ctx: JobContext) {
    console.log('digest slot:', ctx.scheduledAt.toISOString());
  }

  @Every('sync-customers', '10s', { timeoutMs: 8_000 })
  async sync() {}
}
Or without method decorators in NestJS, inject the Scheduler provider and register jobs in onModuleInit:
import { Injectable, type OnModuleInit } from '@nestjs/common';
import { type JobContext, Scheduler } from 'anarchon';

@Injectable()
export class InvoicesService implements OnModuleInit {
  constructor(private readonly scheduler: Scheduler) {}

  onModuleInit(): void {
    this.scheduler.cron('monthly-invoices', '0 6 1 * *', (ctx) => this.buildInvoices(ctx));
  }

  private async buildInvoices(ctx: JobContext): Promise<void> {
    console.log('invoices slot:', ctx.slot, 'attempt:', ctx.attempt);
  }
}
See the NestJS recipe for wiring Scheduler to application startup and shutdown, and check out the runnable NestJS example.
Where this approach fits
| Approach | Runs once per slot across replicas | Takeover on crash (kill -9) |
Extra infra beyond your DB | Best for |
|---|---|---|---|---|
In-process (node-cron, @nestjs/schedule) |
No (fires on every replica) | No | None | Single-instance apps |
| Anarchon | Yes (atomic slot claim) | Yes (lease backends) | None (uses your Redis, Postgres, SQLite, RabbitMQ, or NATS) | Recurring sync, cleanup, reconciliation, and reports inside existing services |
Durable queue (BullMQ, pg-boss) |
Yes | Yes | Worker queue tables / Redis streams | Retaining every individual item as a durable backlog of queued work |
Infra cron (Kubernetes CronJob) |
Yes | K8s job controller | Container registry & K8s cluster | Heavy batch jobs needing dedicated CPU/memory isolation |
The comparison guide discusses these trade-offs in detail.
The project is dual-licensed under AGPLv3 and a separate commercial license (which is free under $500k annual gross revenue). See the licensing page for details.
 aristoteliss
/
anarchon
Distributed cron and interval scheduling with no leader and no distributed locks. One atomic claim selects one instance per scheduled run.
anarchon


Documentation · Quick start · Guarantees and limits · Examples · License
Leaderless scheduling for Node.js clusters. Run the same jobs in every instance; an atomic claim in Redis, Valkey, PostgreSQL or SQLite selects one runner for each scheduled slot. The default lease strategy retries after a runner stops renewing its lease. That gives at-least-once execution after failures, not exactly-once side effects: handlers should be idempotent, and a frozen runner can briefly overlap its replacement.
anarchon also handles what goes wrong in real clusters:
- jobs that run longer than their interval
- an instance crashing or freezing mid-run
- rolling deploys, and every instance restarting at once
import { RedisBackend, Scheduler } from 'anarchon';
const scheduler = new Scheduler({ backend: new RedisBackend({ redis: 'redis://localhost:6379' }) }); // a backend is required: none is assumed

scheduler
.every('sync',…You can also install it from npm and read the full documentation.
If you try the three-process example, which backend would you use for a real job, and what edge cases have you run into when coordinating scheduled work across replicas?


Top comments (0)