


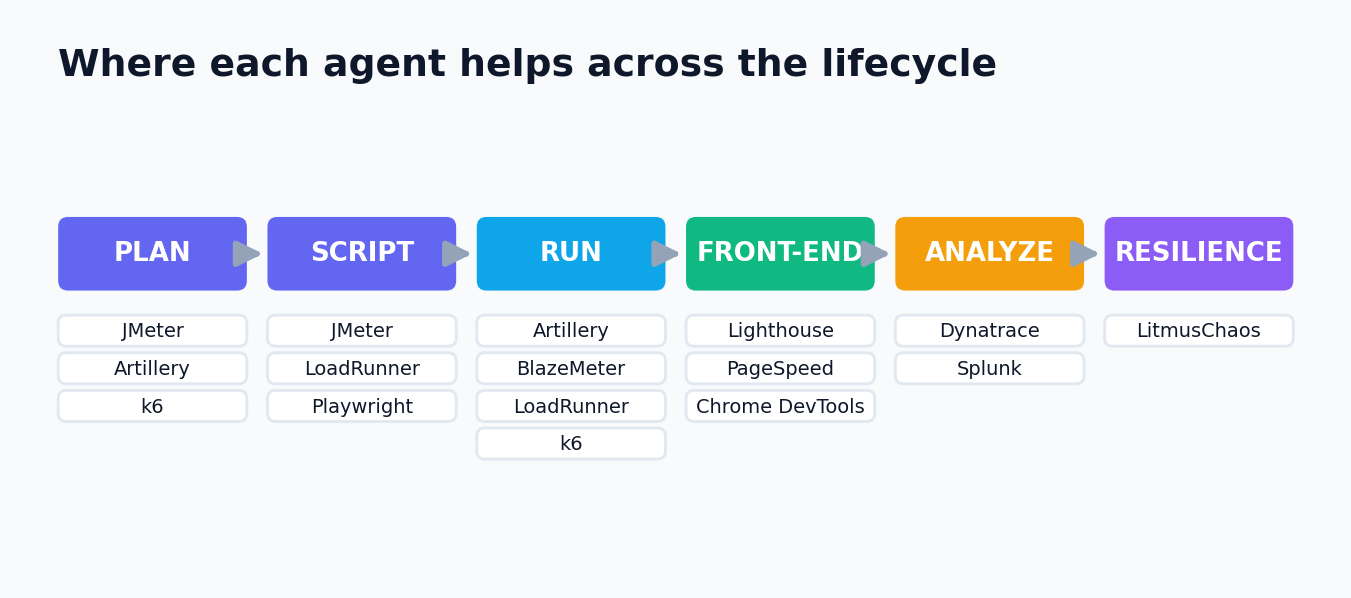
![Where each agent helps across the performance-engineering lifecycle]
3. Load & stress testing
3.1 k6 MCP
-
Repo:
grafana/mcp-k6· Language: Go · Status: 🟢 official (Grafana Labs) — the maintainers mark it experimental -
Runtime: stdio by default, optional Streamable HTTP (
-transport=http) — ships as a Docker image, Homebrew formula, Debian/RPM packages, a native Go binary, or anxk6subcommand -
Config: none required for local use beyond having
k6onPATH(or using the Docker image, which bundles it); HTTP mode adds-addr,-endpoint,-stateless,-preload - Auth: none built in — the README is explicit that a remote deployment needs a trusted network or a proxy in front of it
k6 scripts are JavaScript, and JavaScript is forgiving about compiling into something that silently
does the wrong thing. Plenty of k6 users have shipped a "test" that ran zero real iterations because
of a scenario-config typo, and only found out from a suspiciously fast pass.
Benefits:
-
validate_scriptcatches structural mistakes before you burn a real run on them — a minimal dry run at 1 VU, 1 iteration -
generate_scriptdrafts a starting script from a plain-English description, grounded in the actual k6 docs rather than a stale training snapshot - The documentation tools (
list_sections,get_documentation) let the agent look up the current k6 API instead of guessing at option names - Works the same whether you run it locally via Docker or point your whole team at one shared HTTP instance
Usage in practice: "generate a k6 script that load-tests our login API with authentication, then
validate it" pulls the current k6 docs for scenarios and thresholds, drafts a script, and immediately
runs validate_script against it — catching a bad stages array before you ever spend a real run on
it.
| Tool | Parameters | What it does |
|---|---|---|
validate_script |
script |
Dry-runs the script (1 VU, 1 iteration) and returns pass/fail plus stdout/stderr |
run_script |
script, vus?, duration? (max 5m), iterations?
|
Executes the test locally and returns metrics and a summary |
list_sections |
version?, category?, depth? (default 1, max 5), root_slug?
|
Browses the k6 docs tree without loading all of it into context |
get_documentation |
slug, version?
|
Retrieves the full markdown for one docs section |
There's also a generate_script prompt template (resource URI prompts://k6/generate_script) that
chains research, best practices, and validation into one guided flow.
Good for: going from "describe the test in English" to a validated k6 script without leaving the
conversation — and it's the one server here where the maintainers are upfront that it's still
experimental, so budget for rough edges.
3.2 BlazeMeter MCP
-
Repo:
Blazemeter/bzm-mcp· Language: Python 3.11+ · Status: 🟢 official (published by BlazeMeter/Perforce) -
Runtime options: pre-built binary,
uvx(from git), or Docker (ghcr.io/blazemeter/bzm-mcp) -
Config:
API_KEY_ID+API_KEY_SECRET(or aBLAZEMETER_API_KEYJSON file),SOURCE_WORKING_DIRECTORYfor Docker mounts, optionalSSL_CERT_FILEfor corporate CA bundles
It's the one entry on this list you can point at a compliance review without an argument — a
vendor-maintained server, from the company that makes the product.
Benefits:
- OpenTelemetry ships out of the box, so you get observability into the agent's behavior for free, not just the load test's
- Three install paths (binary,
uvx, Docker) mean it fits whatever your team already standardized on - Cloud-scale execution without you having to run or scale your own load generators
Usage in practice: a quarterly capacity test that used to mean someone manually clicking through
the BlazeMeter console becomes "launch the payments load test in the cloud and tell me how it went" —
the agent starts the run, waits, and reports back with the summary, while OpenTelemetry quietly
records how long each of those calls actually took.
This is the one official, vendor-maintained server in the load-testing category. Its tool surface
covers the full cloud workflow — creating and managing load-test workflows, executing them, and
retrieving reports — but BlazeMeter documents the exact tool list in their own
MCP Server guide
rather than enumerating every tool in the README, so treat the specific tool names as
vendor-documented rather than independently verified here.
Observability bonus: it ships OpenTelemetry instrumentation out of the box — every tool call
produces a trace (tool name, action, client name/version, session ID) and two metrics
(mcp.tool.calls, mcp.tool.duration). Telemetry defaults to BlazeMeter's own collector; you can
redirect it (OTEL_EXPORTER_OTLP_ENDPOINT) or disable it (OTEL_SDK_DISABLED=true or --no-telemetry).
Good for: cloud-scale execution when you're already a BlazeMeter customer and want the vendor's
own supported path.
3.3 LoadRunner Cloud MCP
-
Repo:
pbandreddy/loadrunner-cloud-mcp-server· Language: JavaScript (ESM) · Status: 🔵 community -
Runtime: Node.js 18+ (20+ recommended) ·
@modelcontextprotocol/sdk1.9.0 · stdio by default, optional SSE (--sse) -
Config:
LRC_BASE_URL,LRC_TENANT_ID,LRC_CLIENT_ID,LRC_CLIENT_SECRET, optionalPORT(SSE mode) - Auth: client credentials exchanged for a bearer token automatically before every call
Engineers finish a spike test and then lose the next quarter hour clicking through the LoadRunner
Cloud UI to find the run, open the transactions tab, and eyeball whether p95 crossed the line. This
server exists to compress that click-through into a question.
Benefits:
- No more hunting for a run ID by hand — the tool chain resolves project → test → run for you
- Percentile math (p90/p95) comes back built into the response, not something you compute from a raw CSV export
- Read-only by construction, so pointing an agent at it can't accidentally trigger a new test run
- One call (
test_runs_getHttpResponses) gets you straight to the failure evidence instead of a support ticket
Usage in practice: picture this — your spike test on checkout just finished. Instead of opening a
browser, you ask "did checkout regress in the last run?" The agent resolves the project with
get_projects, walks to the latest run through projects_getLoadTestRuns, then pulls
test_runs_getTestRunTransactions for the percentile table and test_runs_getHttpResponses if
anything looks off. Thirty seconds later you have an answer instead of a browser tab.
This server is read-only — it's built for investigating existing LoadRunner Cloud projects and
runs, not for launching new ones. All nine tools require TENANTID under the hood; you never pass it
yourself.
| Tool | Parameters | What it returns |
|---|---|---|
get_projects |
(none) | All projects in the tenant |
projects_getLoadTests |
projectId |
Load tests for a project |
projects_getLoadTestScripts |
projectId, loadTestId
|
Scripts attached to a load test |
projects_getLoadTestRuns |
projectId, loadTestId
|
Runs for a load test |
get_active_test_runs |
status?, projectIds?
|
Currently active runs, filterable by status (RUNNING, INITIALIZING, CHECKING_STATUS, STOPPING, DELAYED) |
test_runs_getRecentTestRuns |
projectIds? |
License usage for runs in the last 30 days |
test_runs_getTestRunResults |
runId |
Overall result/status for a run |
test_runs_getTestRunTransactions |
runId |
Transaction data — the call always requests the 90th and 95th percentile |
test_runs_getHttpResponses |
runId |
HTTP response detail for a run |
Good for: "what's the p95 on the latest checkout run" style investigation, without opening the
LRC UI.
3.4 Apache JMeter MCP ("JMeter Architect")
-
Repo:
aravindksk7/Jmeter-MCP· Language: TypeScript →dist/index.js· Status: 🔵 community -
Runtime: Node.js 18+ · Apache JMeter itself only required for the run tool, on
PATH -
Config: invoked as
node dist/index.js; JMeter'sbindirectory must be onPATHforjmeter_run_testto work
Ask any engineer who's used JMeter's desktop GUI to add a Header Manager, and you'll get a specific
kind of sigh. This server routes around the GUI entirely.
Benefits:
- No hand-edited XML — the tools assemble a structurally valid
.jmxfor you, element by element - Executes in non-GUI mode from the start, so the same plan you build in chat is the one that runs in CI
- Assertions and listeners are added as explicit tool calls, so nothing gets silently skipped the way it can in a GUI where a checkbox is easy to miss
Usage in practice: "build a 100-user checkout test with a 200-status assertion and run it" turns
into a real sequence: jmeter_init_plan, then a thread group at 100 users, a sampler for the checkout
endpoint, an assertion on the response code, a listener for the aggregate report, and finally
jmeter_run_test. You get a working .jmx and a completed run without opening the JMeter desktop app
once.
This one doesn't call an existing JMeter installation to build a plan — it constructs a real .jmx
file, element by element, then hands it to JMeter to execute in non-GUI mode.
| Tool | Required parameters | What it does |
|---|---|---|
jmeter_init_plan |
filename |
Creates a fresh, empty .jmx test plan |
jmeter_add_thread_group |
filename, num_threads, ramp_time, loops
|
Adds virtual users (loops: -1 = infinite) |
jmeter_add_sampler |
filename, domain, path, method, parameters
|
Adds an HTTP request |
jmeter_add_header |
filename, headers
|
Adds an HTTP Header Manager |
jmeter_add_listener |
filename, listener_type (summary \ |
aggregate \ |
jmeter_add_timer |
filename, delay_ms, random_delay_ms?
|
Adds think time between requests |
jmeter_add_assertion |
filename, test_field (response_data \ |
response_code \ |
jmeter_run_test |
filename, output_file?
|
Executes the plan in non-GUI mode |
Good for: building a correct .jmx from a sentence instead of hand-editing XML — genuinely useful
if you've ever fought JMeter's GUI to add a Header Manager.
3.5 Artillery MCP
-
Repo:
jch1887/artillery-mcp-server· Language: TypeScript · Status: 🔵 community -
Runtime: Node.js 22.18+ · requires the Artillery CLI on
PATH(orARTILLERY_BIN) · stdio -
Config:
ARTILLERY_WORKDIR,ARTILLERY_BIN,ARTILLERY_TIMEOUT_MS(default 1,800,000 ms / 30 min),ARTILLERY_MAX_OUTPUT_MB(default 10),ARTILLERY_ALLOW_QUICK(default true),DEBUG -
Sandbox: every path is resolved inside
ARTILLERY_WORKDIR; the child process environment is an explicit allow-list, not inherited wholesale
Artillery is one of the fastest load tools to spin up, but its CLI output is a wall of JSON you
re-parse by eye after every run, and the YAML configs tend to live wherever the last person who wrote
one happened to save them.
Benefits:
- Saved configs mean "the smoke test for the payments API" lives in one named place instead of six local copies
- Built-in regression thresholds turn "looks about the same to me" into an actual pass/fail
- Sandboxing means you can hand this to a teammate — or an agent — without worrying what paths or env vars it can touch
-
quick_testskips the YAML entirely when you just need to hit an endpoint a few times right now
Usage in practice: before every deploy, someone on the team runs the same smoke test by hand.
Wired up here, that becomes "run the api-smoke baseline and compare it to last week's." The agent
replays the saved config, parses the JSON results into percentiles and error counts, and tells you
plainly whether anything regressed — no spreadsheet required.
Eleven tools, split across running tests and managing saved configurations:
| Tool | Parameters | Notes |
|---|---|---|
run_test_from_file |
path, outputJson?, reportHtml?, env?, cwd?, validateOnly?
|
Runs a config file already inside the workdir |
run_test_inline |
configText, outputJson?, reportHtml?, env?, cwd?, validateOnly?
|
Config as a YAML/JSON string — Artillery 2.0+ requires flow: instead of requests: in scenarios |
quick_test |
target, rate?, duration?, count?, method?, headers?, body?, insecure?, keepResults?, outputJson?
|
No config file needed; generates a one-request scenario |
run_saved_config |
name, outputJson?, reportHtml?, env?, validateOnly?
|
Runs a previously saved config by name |
save_config |
name, content, description?, tags?
|
Stores under $ARTILLERY_WORKDIR/saved-configs/
|
list_configs |
tag? |
Lists saved configs, optionally filtered by tag |
get_config |
name |
Retrieves a saved config's content |
delete_config |
name |
Deletes a saved config |
parse_results |
jsonPath |
Summarizes a results file: RPS, latency percentiles (p50/p95/p99), HTTP codes, error counts, vuser stats |
list_results |
limit? (default 100) |
Lists result files under the workdir, newest first |
list_capabilities |
(none) | Reports Artillery version, server version, transports, and configured limits |
Note on HTML reports: recent Artillery releases removed the report command; if reportHtml is
set and no file appears, the server falls back to returning the JSON path with a warning rather than
failing outright.
Good for: quick load checks and baseline-vs-current regression comparisons, driven entirely from
chat.
4. Observability & evidence
4.1 Dynatrace MCP
-
Repo:
dynatrace-oss/dynatrace-mcp· Language: TypeScript · License: MIT -
Status: ⚫ deprecated — final release was v2.1.2, no further updates. Migrate to
Dynatrace-for-AI +
dtctlfor local use, or the Dynatrace Remote MCP Server for remote/agent-to-agent scenarios. The tool contract below is still representative of the pattern. -
Runtime: Node.js 24+ · npm package
@dynatrace-oss/dynatrace-mcp-server· stdio by default, or--httpfor an HTTP/bearer-token mode Config:DT_ENVIRONMENT(required — the Platform URL,…apps.dynatrace.com, not the classic…live.dynatrace.com),DT_PLATFORM_TOKENorOAUTH_CLIENT_ID/OAUTH_CLIENT_SECRET(optional — otherwise browser OAuth + OS keychain),DT_GRAIL_QUERY_BUDGET_GB(default 1000),DT_SSO_URL(optional override)
DQL is powerful and genuinely has a learning curve; the natural-language generate/verify/explain tools
exist specifically so you don't have to memorize it to get an answer out of Grail.
Benefits:
-
generate_dql_from_natural_language+verify_dqlmeans you get a query you can actually read before it runs against your data - The Grail budget (
DT_GRAIL_QUERY_BUDGET_GB) turns "oops, that scanned way more than I meant" from a bill into a warning - Davis AI (
chat_with_davis_copilot) is there for the "what does this actually mean" follow-up question a raw query result can't answer
Usage in practice: "during the checkout load test window, latency spiked — what happened?"
resolves the service, generates and verifies a DQL query scoped to just that window, and
cross-references list_problems and list_exceptions for the same period — landing on a concrete,
correlated answer instead of a wall of log lines.
Capabilities are grouped by function (the README doesn't present them as a flat numbered list, but
these are every tool named in the source docs):
| Group | Tools |
|---|---|
| Observability & problems |
list_problems · list_vulnerabilities · list_exceptions · get_kubernetes_events
|
| Grail queries |
execute_dql · verify_dql · generate_dql_from_natural_language · explain_dql_in_natural_language
|
| Entity discovery | find_entity_by_name |
| Davis AI |
chat_with_davis_copilot · list_davis_analyzers · execute_davis_analyzer
|
| Automation & sharing |
send_slack_message · send_email · send_event · create_dynatrace_notebook
|
Cost matters here: execute_dql scans Grail storage, billed by volume scanned. The server tracks
usage against DT_GRAIL_QUERY_BUDGET_GB per session and warns at 80% of budget. You can audit actual
consumption with a DQL query against dt.system.events filtered to
client.client_context containing "dynatrace-mcp".
Required OAuth scopes vary by tool — at minimum app-engine:apps:run for nearly everything, plus
the specific storage:*:read scope for whatever Grail data type you're querying (logs, metrics,
spans, entities, events, etc.), davis-copilot:*:execute for the AI features, and email:emails:send
/ document:documents:* for the sharing tools.
Good for: correlating a load-test window with production problems and exceptions via DQL — the
worked example in the companion post walks through exactly this.
4.2 Splunk MCP
-
Repo:
livehybrid/splunk-mcp· Language: Python - Status: ⚫ archived — the README now points to Splunk's official MCP Server on Splunkbase (app 7931). The tool list below reflects the archived community project; use it to understand the shape of a Splunk MCP integration, not as a production recommendation.
-
Runtime: Python, built on FastMCP · three operating modes: SSE (default), REST API
(
python splunk_mcp.py api), or stdio (python splunk_mcp.py stdio) -
Config:
SPLUNK_HOST,SPLUNK_PORT(default 8089),SPLUNK_TOKEN(orSPLUNK_USERNAME+SPLUNK_PASSWORD),SPLUNK_SCHEME(default https),VERIFY_SSL(default true),FASTMCP_LOG_LEVEL
Even though the community server here is archived, understanding its shape is exactly what lets you
evaluate Splunk's official replacement with open eyes instead of starting from zero.
Benefits:
- Consistent error handling across every tool means a failed search or a permissions issue comes back as something you can actually act on, not a stack trace
- The KV Store tools double as a lightweight state store for automation, a nice trick if you're already scripting around Splunk
- Three transport modes (SSE, REST API, stdio) mean it can fit into however your team's tooling already talks to services
Usage in practice: during an incident, "search the last 30 minutes for checkout errors and
summarize the affected sourcetypes" runs search_splunk scoped to that window, cross-references
indexes_and_sourcetypes to explain where the noise is coming from, and gives you a triage-ready
summary instead of a raw search-results table.
Thirteen tools across five functional groups:
| Group | Tools |
|---|---|
| Meta | list_tools |
| Health |
health_check (lists reachable Splunk apps) · ping
|
| Users |
current_user · list_users
|
| Indexes |
list_indexes · get_index_info (params: index_name) · indexes_and_sourcetypes
|
| Search |
search_splunk (params: search_query, earliest_time?, latest_time?, max_results?) · list_saved_searches
|
| KV Store |
list_kvstore_collections · create_kvstore_collection (params: collection_name) · delete_kvstore_collection (params: collection_name) |
Error handling is consistent across the tool set: invalid searches, permission failures, missing
resources, and bad input all return a structured error message rather than a bare exception.
Good for: understanding the pattern (search + index introspection + KV store) if you're
evaluating whether to build against Splunk's now-official server instead.
5. Resilience & chaos
5.1 LitmusChaos MCP
-
Repo:
litmuschaos/litmus-mcp-server· Language: Go · Status: 🟢 official (LitmusChaos project) - Runtime: connects to a running LitmusChaos ChaosCenter (3.x) over its GraphQL API
-
Config:
CHAOS_CENTER_ENDPOINT,LITMUS_PROJECT_ID,LITMUS_ACCESS_TOKEN, optionalDEFAULT_INFRA_ID, optionalDEFAULT_ENVIRONMENT_ID
Chaos engineering has a well-earned reputation as YAML archaeology — CRDs, manifests, and
infrastructure wiring before you even get to break anything on purpose. This collapses all of that
into a sentence.
Benefits:
- Seventeen tools cover the whole lifecycle, from discovering faults in a ChaosHub to registering
infrastructure to reading back a resiliency score — you're not stitching together
kubectlcommands by hand - Resiliency scoring gives you a number you can actually track release over release, not just a pass/fail
- It plugs into existing ChaosHub content, so you're not authoring fault definitions from scratch every time
Usage in practice: before a release, "run a pod-delete on checkout-service in staging for 30
seconds and tell me the resiliency score" starts the experiment, polls its status, checks the probes
attached to it, and reports back a number and a verdict — the entire chaos-engineering loop, in one
exchange.
The largest tool surface in this list — 17 tools — grouped into six functional areas:
| Group | Tools (by function) |
|---|---|
| Chaos experiments | list experiments · get experiment details · run an experiment · stop an experiment |
| Execution monitoring | list runs · get run details · retrieve execution logs · monitor run status |
| Infrastructure | list registered infrastructure · get infrastructure details · register new infrastructure · install manifests |
| Environments | create an environment · list environments · manage infra-to-environment associations |
| Resilience probes | HTTP probes · command (CMD) probes · Kubernetes probes · Prometheus probes |
| ChaosHub & discovery | list ChaosHubs · get fault details · discover available experiments |
Target infrastructure is Kubernetes/OpenShift; target applications are typically microservices,
databases, APIs, and messaging systems. Repository layout for the server itself: main.go (server
setup), handlers.go (tool handlers), go.mod, a Dockerfile, and a Makefile.
Good for: "run a pod-delete on the checkout service for 30 seconds and tell me the resiliency
score" — the whole point of chaos engineering, minus the YAML and CRDs.
6. Front-end / client-side testing
6.1 Chrome DevTools MCP
-
Repo:
ChromeDevTools/chrome-devtools-mcp· Language: TypeScript · Status: 🟢 official (the Google Chrome DevTools team) -
Runtime: Node.js LTS, current stable Chrome · install via
npx -y chrome-devtools-mcp@latest -
Config:
--headless,--isolated,--slim(basic-only tool set),--no-performance-crux(disable CrUX lookups),--no-usage-statisticsorCHROME_DEVTOOLS_MCP_NO_USAGE_STATISTICS(opt out of telemetry),CHROME_DEVTOOLS_MCP_NO_UPDATE_CHECKS - Auth: none — it drives a local (or connected) Chrome instance directly via Puppeteer
This is the biggest tool surface in the whole catalog — 58 tools — because it isn't just a
performance tool, it's the entire DevTools panel exposed to an agent: Performance, Network, Elements,
Memory profiling, even PWA install/launch and browser extension management.
Benefits:
- Real Chrome performance traces (
performance_start_trace/performance_stop_trace/performance_analyze_insight) give you actual Core Web Vitals data, not an estimate -
lighthouse_auditcovers accessibility, SEO, best practices, and "agentic browsing" in the same session as your performance trace — one browser, one context, several kinds of evidence - The accessibility-tree snapshot (
take_snapshot) lets an agent click, fill, and navigate a real page reliably, without brittle pixel coordinates - Ships from the same team that builds DevTools itself, so it tracks Chrome's actual internals rather than reverse-engineering them
Usage in practice: "check the performance of the checkout page and tell me what's hurting LCP"
navigates to the page, starts a trace with performance_start_trace (reload enabled), stops it, and
calls performance_analyze_insight for the specific insight — usually something concrete like
render-blocking CSS or an oversized hero image, backed by the same trace data you'd get by hand in
DevTools.
The full reference lists all 58 tools; the groups most relevant to performance and front-end testing:
| Group | Tool count | Examples |
|---|---|---|
| Performance | 3 |
performance_start_trace, performance_stop_trace, performance_analyze_insight
|
| Network | 2 |
list_network_requests, get_network_request
|
| Debugging | 9 |
lighthouse_audit, take_snapshot, take_screenshot, evaluate_script, get_css_styles
|
| Navigation automation | 6 |
navigate_page, new_page, wait_for, list_pages
|
| Input automation | 10 |
click, fill, fill_form, hover, press_key, upload_file
|
| Emulation | 2 |
emulate (viewport, network throttling, dark mode), resize_page
|
| Memory | 13 | heap snapshot capture, comparison, and querying |
| Extensions, third-party tools, WebMCP, PWA | 13 combined | browser extension and installed-app management |
Good for: the same "audit this page" job as Lighthouse MCP, but backed by real trace data and the
option to drive the page first (log in, add items to a cart, then trace the checkout flow) instead of
only auditing a cold page load. Use --slim if you want the input/navigation/debugging basics without
the full 58-tool surface.
6.2 Lighthouse MCP
-
Repo:
priyankark/lighthouse-mcp· Language: TypeScript · Status: 🔵 community -
Runtime: Node.js 22.19+, Chrome/Chromium (sandboxed) · install via MCP Registry,
npx lighthouse-mcp, or global npm -
Config:
AUDIT_ALLOW_LOOPBACK(default true; setfalsefor hosted/public-only audits)
Next to Chrome DevTools MCP's 58 tools, it's genuinely refreshing that this one only has two —
sometimes you just want a score, not a workflow.
Benefits:
- SSRF and DNS-rebinding protections are on by default, so it's safe to expose this to a shared bot or a hosted worker
- Fast enough to run on every pull request without anyone noticing the extra time
- Mobile-first defaults, which matches where most real users actually are
Usage in practice: a PR touching the checkout page triggers "audit this page on mobile and tell me
the top fixes." run_audit comes back with a score and a category breakdown; if all you need is the
headline number, get_performance_score skips the rest of the audit and answers in a fraction of the
time.
Deliberately minimal — two tools, both wrapping Google Lighthouse directly:
| Tool | Parameters | Notes |
|---|---|---|
run_audit |
url, categories? (performance, accessibility, best-practices, seo — default all), device? (mobile default \ |
desktop), throttling? (default true) |
get_performance_score |
url, device?
|
Performance score only — faster than a full audit |
Safety model, worth calling out explicitly: Chrome runs sandboxed; loopback/private/link-local/
cloud-metadata destinations are blocked by default (redirects included) to prevent SSRF and DNS
rebinding; audits are serialized one-at-a-time with a 120-second timeout; Chrome and the audit proxy
are torn down after every run, success or failure.
Good for: a fast "what's wrong with this page" check, safe enough to point at a hosted worker.
6.3 PageSpeed Insights MCP
-
Repo:
ruslanlap/pagespeed-insights-mcp· Language: TypeScript · Status: 🔵 community -
Runtime: Node.js 20.19+ ·
npx -y pagespeed-insights-mcp, npm global, or Docker -
Config:
GOOGLE_API_KEY(with the PageSpeed Insights API enabled in Google Cloud Console)
Lighthouse alone tells a small lie — it's a lab measurement over a throttled connection, which is
pessimistic by design. PageSpeed adds the real-user CrUX data that says what's actually happening in
production, so the two together stop you from either overreacting to a lab number or ignoring a real
regression.
Benefits:
- Lab and field data live behind one conversational interface instead of two separate dashboards
- Built-in baseline comparison means "did the release regress?" is a single tool call, not a manual diff
- Batch analysis triages up to ten pages at once, which matters the moment you're auditing more than a homepage
Usage in practice: after a release, "compare mobile performance of the old and new build and
prioritize the fixes" runs pagespeed_analyze_page against both, pulls pagespeed_get_field_data for
the real-user view, and hands back a ranked list — usually something unglamorous like an unoptimized
hero image or a blocking third-party script.
Version 2 of this server deliberately replaced 19 endpoint-shaped tools with six workflow tools —
worth knowing if you find v1 examples online, since the old tool names no longer exist.
| Tool | Key parameters | What it covers |
|---|---|---|
pagespeed_analyze_page |
url, strategy (mobile/desktop), report (full \ |
summary \ |
pagespeed_diagnose_page |
url, focus (visual \ |
elements \ |
pagespeed_get_field_data |
url or origin, scope (page \ |
origin) |
pagespeed_compare_pages |
two URLs, or one URL + mode: baseline
|
Page-vs-page or page-vs-saved-baseline comparison |
pagespeed_analyze_batch |
1–10 URLs | Triage many pages at once, with progress notifications where the client supports it |
pagespeed_clear_cache |
(none) | Clears the in-memory API-response cache (useful right after a deploy) |
Every data-returning tool accepts responseFormat: markdown (default) or json, and results come back
as structured MCP structuredContent, not just prose.
Good for: combining lab results (Lighthouse, throttled and therefore pessimistic) with field
results (CrUX, what real visitors experienced) in the same conversation — the README's own example
shows GitHub.com scoring 54/100 in the lab while CrUX shows real users seeing a 1.9s FCP, which is a
good illustration of why you want both.
7. Automation
7.1 Playwright MCP
-
Repo:
microsoft/playwright-mcp· Language: TypeScript · Status: 🟢 official (Microsoft) — source lives in the main Playwright monorepo -
Runtime: Node.js 18+ · install via
npx @playwright/mcp@latest -
Config:
--browser(chrome/firefox/webkit/msedge),--headless,--isolated(fresh profile per session) or persistent profile (default),--device/--mobileemulation,--caps vision,pdf,devtoolsfor optional extra capabilities,--cdp-endpointto attach to an already-running browser,--allowed-origins/--blocked-originsfor network scoping -
Auth: none by default — trust boundaries are enforced through
--allowed-origins/--blocked-originsand the workspace-root file-access restriction, not credentials
This is the server this workspace's own LoadRunner Agent framework already leans on: the
lr-record-auto and lr-record-manual skills drive Playwright MCP to record a real UI journey, and
lr-generate-har replays it headlessly to produce the HAR that feeds LoadRunner UI Vuser script
generation. If you're already scripting browser automation for that pipeline, this is the same tool —
you don't need a second one for general-purpose browser automation.
Benefits:
- Works off the accessibility tree by default, not screenshots — faster, more deterministic, and it doesn't need a vision-capable model
-
--isolatedsessions give you a clean-slate browser for every recording, so cookies and login state from a previous run can't leak into the next one -
--cdp-endpointlets you attach to a browser you already launched — useful for recording against a real, already-authenticated session instead of automating a fresh login every time - The same server doubles as your UI-automation recorder and your day-to-day "go check this page for me" browser agent — one integration, two jobs
Usage in practice: ask it to "log into staging, add an item to the cart, and go to checkout" and it
takes a snapshot of the page, clicks and fills using the accessibility tree, and can hand that journey
off as the seed for a LoadRunner Web Vuser script — the exact loop this repo's lr-record-auto skill
automates end to end.
| Category | Representative tools | Notes |
|---|---|---|
| Navigation & interaction |
browser_navigate, browser_click, browser_type, browser_hover, browser_press_key, browser_select_option, browser_drag, browser_file_upload
|
Structured, accessibility-tree-driven actions |
| Inspection |
browser_snapshot, browser_take_screenshot, browser_console_messages, browser_network_requests, browser_evaluate
|
Read the page state without guessing from pixels |
| Session & tabs |
browser_tabs, browser_wait_for, browser_resize, browser_close, browser_install
|
Multi-tab and lifecycle management |
The exact tool list ships with the server and is documented in full in its own reference — treat the
names above as the stable, widely-referenced surface rather than an independently re-verified list from
source in this pass, the same treatment given to BlazeMeter's tool names earlier.
Good for: the automation category exists because of this one server — general-purpose browser
scripting that happens to be the same tool this repo's own UI-recording pipeline is built on, so wiring
it in once covers both "record a user journey for load testing" and "go check something on this page
for me."
8. Server comparison at a glance
| Server | Category | Status | Language | Tool count | Transport |
|---|---|---|---|---|---|
| k6 | Load & stress | 🟢 official | Go | 4 | stdio / HTTP |
| BlazeMeter | Load & stress | 🟢 official | Python | cloud workflows (vendor-documented) | stdio / HTTP |
| LoadRunner Cloud | Load & stress | 🔵 community | JavaScript | 9 | stdio / SSE |
| Apache JMeter | Load & stress | 🔵 community | TypeScript | 8 | stdio |
| Artillery | Load & stress | 🔵 community | TypeScript | 11 | stdio |
| Dynatrace | Observability | ⚫ deprecated | TypeScript | 15 | stdio / HTTP |
| Splunk | Observability | ⚫ archived | Python | 13 | stdio / SSE / API |
| LitmusChaos | Resilience | 🟢 official | Go | 17 | GraphQL-backed |
| Chrome DevTools MCP | Front-end | 🟢 official | TypeScript | 58 | stdio |
| Lighthouse | Front-end | 🔵 community | TypeScript | 2 | stdio |
| PageSpeed Insights | Front-end | 🔵 community | TypeScript | 6 (v2) | stdio |
| Playwright MCP | Automation | 🟢 official | TypeScript | 20+ (vendor-documented) | stdio |
140+ independently-catalogued tools across ten servers, plus two more (BlazeMeter, Playwright) with
vendor-documented tool surfaces — twelve servers, five categories, and that's before anyone writes the
agent layer on top of them.
9. What trips people up in practice
These are the specific things that cause a working integration to quietly break, not a generic
best-practices list:
-
The docs can undersell the tool list. LoadRunner Cloud's README doesn't mention
test_runs_getRecentTestRuns, but it's fully wired and returns real license-usage data. Check what your MCP client actually discovers at connection time before assuming a capability isn't there. -
Old tool names stop working silently. PageSpeed Insights replaced 19 endpoint-shaped tools with
6 workflow tools in its v2 release. Any example referencing the old names (
analyze_page_speed,get_recommendations, etc.) will fail against a current install — check the version before you copy a snippet. - Two of these servers are past end-of-life. Dynatrace's and Splunk's community servers are both deprecated or archived. The tool contracts are still useful to learn from, but point production traffic at the vendor's current offering instead.
-
Cost-bearing tools need a budget before you use them, not after.
execute_dql(Dynatrace) scans Grail storage by volume. Nothing stops a broad query across 90 days of data the first time someone asks a vague question — set the budget first. -
Not every tool is safe to auto-run. Several servers mix read tools with ones that have real side
effects —
send_email,send_slack_message,create_kvstore_collection,delete_kvstore_collection. The tool schema itself won't tell you which is which; you have to decide that before wiring one up. - SSE and stdio aren't interchangeable. LoadRunner Cloud and Splunk both support multiple transports, but with different startup flags and, in Splunk's case, different default behavior per mode. Check the mode-specific section, not just the quickstart.
-
A single official server can dwarf all the others combined. Chrome DevTools MCP alone exposes 58
tools — more than every other server in this catalog put together. If your client loads every tool
schema into context by default, use
--slimor an explicit allow-list instead of eating that cost on every request. -
Playwright's persistent profile is exclusive. Only one browser instance can use the default
persistent profile at a time; running two MCP clients against the same workspace will conflict. Use
--isolatedor a distinct--user-data-dirfor parallel sessions.
10. Production considerations
A short checklist worth running before any of these servers goes anywhere near a shared environment:
- Pin tool names, don't trust discovery blindly. MCP's dynamic tool listing means a server operator can rename or remove a tool at any time. If your integration depends on a specific tool existing, maintain an explicit allow-list and fail loudly if it's missing, rather than silently adapting to whatever the server currently exposes.
-
Cap cost-bearing queries. Dynatrace exposes
DT_GRAIL_QUERY_BUDGET_GBfor exactly this reason — use it, and default to short timeframes (12–24h) rather than open-ended windows. - Gate side-effecting tools behind approval. Anything that sends a message, creates a resource, or deletes data should require an explicit human or policy-engine confirmation, the same way you'd gate a write-capable API call in any other system.
-
Verify auth scope requirements up front. Dynatrace alone has more than a dozen distinct OAuth
scopes depending on which tools you use (
storage:logs:read,storage:spans:read,davis-copilot:*:execute, and so on) — request only what the tools you actually use require. - Track server status over time. A server that's 🔵 community-verified today can become ⚫ archived next quarter (as happened to Splunk's). Revisit this catalog's status column periodically rather than treating it as a one-time check.
- Don't stand up a second browser-automation server. If a team already wires up Playwright MCP for UI-script generation (as this repo's LoadRunner Agent framework does), reuse that connection instead of adding Chrome DevTools MCP or a third browser tool for the same job — decide which one owns browser automation and route everything through it.
None of this — the tool names, the parameters, the trust tiers — matters on its own. What matters is
what happens once one of these is wired into a Copilot agent with a clear job and a few guardrails: a
ninety-minute investigation turns into a two-minute conversation, and a tool you'd otherwise have to
look up becomes a capability your team just has. The companion posts in this series walk through
exactly that wiring, with a full worked example against Dynatrace — the config, the agent
instructions, and a real conversation, not just a table of tool names.
Part 2 is coming — a follow-up post on building the actual GitHub Copilot custom agents that sit
in front of these MCP servers: the agent files, the tool-order and guardrail decisions, and worked
examples beyond Dynatrace.
11. Credits & references
Every project below is third-party open source. Thank you to the maintainers — please check each
repository's license and current maintenance status before depending on it in production.
- k6 — https://github.com/grafana/mcp-k6
- BlazeMeter — https://github.com/Blazemeter/bzm-mcp
- LoadRunner Cloud — https://github.com/pbandreddy/loadrunner-cloud-mcp-server
- Apache JMeter — https://github.com/aravindksk7/Jmeter-MCP
- Artillery — https://github.com/jch1887/artillery-mcp-server
- Dynatrace — https://github.com/dynatrace-oss/dynatrace-mcp (deprecated → Dynatrace-for-AI / dtctl / Remote MCP Server)
- Splunk — https://github.com/livehybrid/splunk-mcp (archived → official app 7931)
- LitmusChaos — https://github.com/litmuschaos/litmus-mcp-server
- Chrome DevTools MCP — https://github.com/ChromeDevTools/chrome-devtools-mcp
- Lighthouse — https://github.com/priyankark/lighthouse-mcp
- PageSpeed Insights — https://github.com/ruslanlap/pagespeed-insights-mcp
- Playwright MCP — https://github.com/microsoft/playwright-mcp (source in microsoft/playwright)
This post is a companion to "A Field Guide to MCP Servers for Performance Engineering",
which covers the agent-design pattern and a worked Dynatrace example. This one is the reference you
come back to when you're deciding which server to wire up next. **Part 2* picks up from here and
walks through building the Copilot agents themselves.*


Top comments (0)