


Collect what you need, only when you need it
Sidekick is an open source live application debugger that comes with many built-in features to make data collection both easier and more efficient. Collecting snapshots and generating logs from running applications are powerful for learning how your code works as long as you collect the data you need.
Logging everything is not a smart move as you can find yourself searching in a log pile full of mostly unnecessary logs in a very short time. Similar case applies for the snapshots & traces. That is why we have included conditional data generation in Sidekick. Combined with hit and time limits, they allow you to collect only what you need, leaving a graveyard of useless data behind.
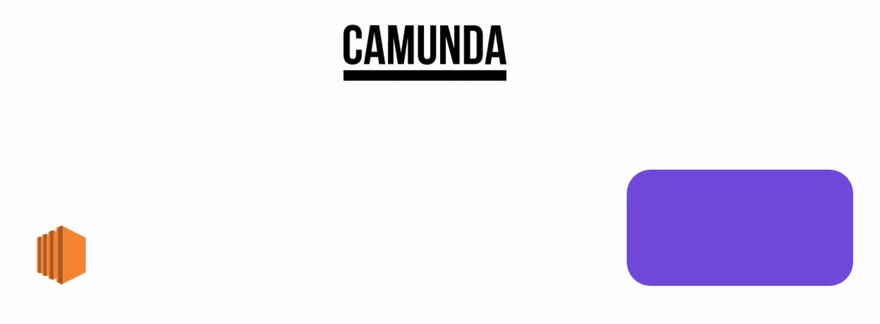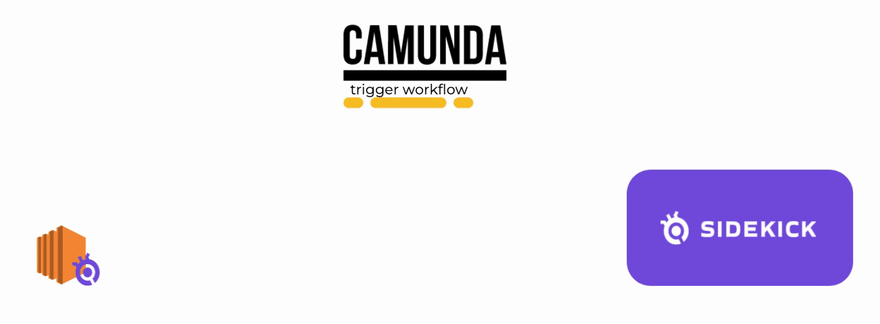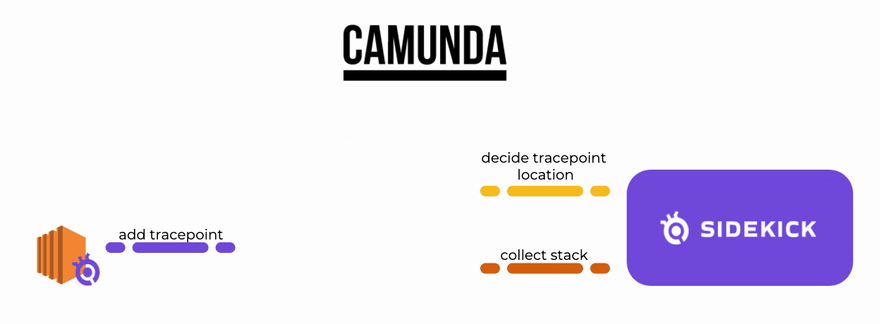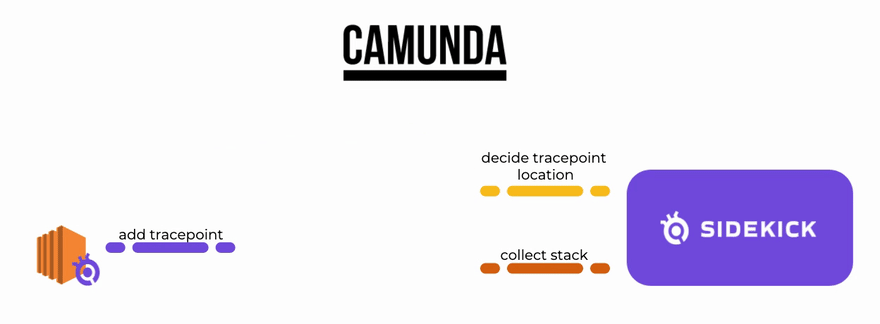
In addition to our out-of-the-box conditional limitation features, Sidekick’s API’s and clients let you to bring your own rules which leads to a relatively new approach to observability, a rule based one. With this approach we will be able to put tracepoints when rules met and start collecting data automatically based on rule engine’s output.
Rule Engines
There are plenty of different rule engines & workflow automation tools that we can use for such a scenario. A few can be listed as:
The Universal Process Orchestrator | Camunda
Camunda's process automation platform allows developers to design, automate and improve processes. Start your free trial today.
 camunda.com

Drools - Drools - Business Rules Management System (Java™, Open Source)
Drools introduces the Business Logic integration Platform which provides a unified and integrated platform for Rules, Workflow and Event Processing.
 drools.org
json-rules-engine - npm
Rules Engine expressed in simple json. Latest version: 6.1.2, last published: a year ago. Start using json-rules-engine in your project by running `npm i json-rules-engine`. There are 102 other projects in the npm registry using json-rules-engine.
 npmjs.com
node-rules - npm
Business Rules Engine for JavaScript. Latest version: 7.2.0, last published: 24 days ago. Start using node-rules in your project by running `npm i node-rules`. There are 15 other projects in the npm registry using node-rules.
npmjs.com
We will be using Camunda for this example for broader use cases as Camunda is more than a rule engine it is a universal process orchestrator. For a usage example of Camunda you can check out:
Use Camunda as an easy-to-use REST-based orchestration and workflow engine (without touching Java)
Using Sidekick with Camunda
Camunda provides external task clients that allow developers to implement tasks to run when a workflow hits to the related step. We will be using Node.js client but cases below can also be achieved with different clients of Camunda and Sidekick’s upcoming Python & Java clients.
camunda-external-task-client-js - npm
Implement your [BPMN Service Task](https://docs.camunda.org/manual/latest/user-guide/process-engine/external-tasks/) in NodeJS.. Latest version: 2.2.0, last published: 5 months ago. Start using camunda-external-task-client-js in your project by running `npm i camunda-external-task-client-js`. There are 15 other projects in the npm registry using camunda-external-task-client-js.
npmjs.com
Example task method:
// Subscribe to the topic: 'topicName'
client.subscribe("topicName", async function({ task, taskService }) {
  // Put your business logic
  // Complete the task
  await taskService.complete(task);
});
@runsidekick/sidekick-client - npm
Sidekick Node.js Client. Latest version: 0.0.2, last published: a month ago. Start using @runsidekick/sidekick-client in your project by running `npm i @runsidekick/sidekick-client`. There are no other projects in the npm registry using @runsidekick/sidekick-client.
npmjs.com
Task method with Sidekick Put tracepoint event:
// Subscribe to the topic: 'topicName'
client.subscribe("topicName", async function({ task, taskService }) {    const params= {
      applicationFilters: [
          {
            name: "Demo application",
            version: "v1.0",
            stage: "prod"
          }
        ],
      fileName: "gitlab.com/repos/...",
      lineNo: 23,
      expireSecs: -1,
      expireCount: -1,
      enableTracing: true,
      persist: true
  }
  apiClient.putTracepoints(params);
  await taskService.complete(task);
});
Example use cases
Case 1 — Activating Tracepoints based on error scenarios
Camunda’s DMN engine provides us ability to define rules in an excel like interface.

Sidekick DMN
As you can observe at the DMN above we can define where we put tracepoints when a certain type of error occurs.
Triggering workflows with error types makes a great use case as it enables us to automatically start collecting extra information based on different cases. Enabling different tracepoints at once is especially useful for spotting state changes.
Note: In addition to this use case Sidekick Node.js agent has ability to automatically capture error stacks, without any tracepoint. check out: https://www.npmjs.com/package/@runsidekick/sidekick-agent-nodejs

Example Sidekick BPMN
Case 2 —Putting Tracepoints on workflow errors

Camunda comes with an error handling mechanism that lets you run actions in cases of errors. In addition to Sidekick client, we can also attach Sidekick agents to task services to observe their state changes and debug them effectively.
Case 3 — Activating Tracepoints on certain events

Last but not least, Sidekick Actions bring more than debugging to the table. They are also great tools to understand how the system works. Especially for the cases like understanding why and how edge cases occur or understanding when does a certain step is reached.
We have briefly explained how Sidekick can be used with Camunda to achieve rule based observability, for better understanding systems, having a smoother debug experience and lowering monitoring costs with conditional data collection. The 3 cases we have explained are just the tip of the iceberg and there is a lot more to discover here.
Please let us know your invaluable ideas because they will guide us on our path to discovering the future of application observability. You can get in touch with us through Twitter, and join our Discord community.


Top comments (1)
Nice use of BPMN as the trigger layer for observability, rather than the thing being observed. Two practical notes from working with Camunda flows:
Correlate the snapshot with the process instance. Inside the external task handler you already have task.processInstanceId and task.businessKey. Passing them along as tags or metadata when you put the tracepoint means that, when it fires, you know exactly which instance triggered it. Otherwise you end up with debug data that’s hard to map back to the business case that caused it.
Be careful with unlimited tracepoints in prod. The example uses stage: "prod" with expireSecs: -1 and expireCount: -1. For rule-triggered tracepoints, a sensible hit/time limit is a good default, both for overhead and because snapshots on production paths can capture personal or payment data you didn’t mean to collect.
Interesting to see the flow going in the opposite direction from what I usually work on: here the process model drives what gets observed, while discovery tools go from observed behaviour back to a process model. Feels like there’s room for both to meet: the same traces that help debug an instance could tell you how the process actually runs compared with the model.
Also worth noting for readers today: the external task pattern here is Camunda 7. On Camunda 8 the equivalent would be a job worker on Zeebe, so the snippet would need adapting.